How regulated, internationally-distributed AI startups can capture the economics of the open-weight era without handing their crown jewels — or their compliance posture — to someone who can log it, price it, or switch it off.
Hunter Alpha Rises — Image by Gemini
On March 11, 2026, a model with no name worth knowing appeared on OpenRouter.
It was labeled “Hunter Alpha.” No developer, no company, no blog post, no website. OpenRouter tagged it a “stealth model” and moved on. It was free. It had a one-million-token context window. It was tuned, obviously and almost aggressively, for agents — the kind of multi-step, tool-calling, plan-execute-revise workloads that chew through tokens by the hundreds of thousands.
Developers did what developers do when something powerful is suddenly free: they pointed everything they had at it. Within days, Hunter Alpha had vaulted to the top of OpenRouter’s usage charts, crossing a trillion tokens in total consumption and outrunning models from labs with nine-figure marketing budgets and household names.
Nobody knew who built it. The leading theory was DeepSeek quietly stress-testing its next system — because at this point, any anonymous model that performs well gets the DeepSeek label by reflex.
On March 18, the mystery ended. Xiaomi’s AI division confirmed that Hunter Alpha was an early internal build of its flagship MiMo-V2-Pro, a roughly one-trillion-parameter mixture-of-experts model (only about 42 billion parameters active per forward pass — the trick that keeps inference cheap) led by a team under Luo Fuli, a former core contributor to DeepSeek’s breakthrough work who’d jumped to Xiaomi a few months earlier.
It was a clinic. A masterclass in how the new game is played. And if you run a startup — especially a small, internationally-distributed one working in a regulated domain — the temptation is to read the obvious lesson off the surface: the cheap models won, so go cheap.
That reading will get your startup killed. Not metaphorically. In your specific industry, it’s the move that ends deals before they start.
The real lesson is deeper, more durable, and — this is the part that should make you sit up — it is the lesson that finally makes a lean, distributed, regulated startup more competitive than the incumbent it’s trying to outrun, not less. Let me walk you through it.
Part 1: The board actually flipped
First, the macro story, because it’s real and it’s the ground everything else stands on.
For most of 2025, American models owned the developer market. On OpenRouter — the neutral routing layer that lets developers send API calls across hundreds of models through one endpoint, which makes it one of the cleaner public signals of what people actually run in production rather than what they say in surveys — US labs commanded something like 70% of top-model usage.
That era ended in February 2026. In the week of February 9–15, Chinese-developed models processed 4.12 trillion tokens on OpenRouter against 2.94 trillion for US models. It was the first time Chinese systems outpaced American ones on the platform. It was not a fluke; the following week the gap widened, and it kept widening. By mid-2026, depending on whose cut of the data you read, US share of top-model token volume had fallen from roughly 70% to roughly 30%, with combined Chinese providers — DeepSeek, Tencent, Xiaomi, MiniMax, Qwen — running the majority of tokens through the busiest workload categories.
Be precise about what that does and doesn’t mean, because the headline numbers get stretched by people with an axe to grind. The widely-quoted “61%” figure refers to share among the top ten most-used models in a single week, not across all 400-plus models on the platform, and not across the entire global API market. OpenRouter’s own longer-horizon study of 100 trillion tokens put Chinese open-weight share closer to 30% of total weekly volume by mid-2025. And volume is not revenue: the premium American labs still capture a wildly disproportionate share of the money even as they bleed tokens, because two markets are forming side by side — a commodity race where the cheapest adequate model wins, and a premium tier where enterprises pay a multiple for frontier reasoning, safety, and support.
But strip away the nuance and one fact survives intact: the center of gravity in production AI usage moved, and it moved because of one thing — cost-per-task in the agent era.
Here is the mechanism, and it’s worth internalizing because it’s the engine under everything that follows. AI usage shifted from chat to agents. On OpenRouter, programming and agentic workloads went from roughly 11% of token volume in early 2025 to more than half. A chat turn is a few thousand tokens. A single agentic run — an autonomous loop that plans, calls tools, writes, tests, reads its own output, and revises, over and over, overnight — can invoke a model thousands of times and burn through a million tokens before breakfast.
When that is your usage pattern, per-token price stops being a line item and becomes the entire budget. A model that’s “10% as good but 5% of the cost” is, for a huge swath of production work, simply the correct business decision. The market didn’t fall out of love with capability. It fell in love with throughput it could afford.
Developers turned out to be loyal to exactly one thing: what works, at a price they can run at scale. Everything else — brand, benchmark crowns, national flags — was sentiment.
That’s the flippening. Now here’s why the obvious conclusion is a trap.
Part 2: The trap inside the opportunity
Hunter Alpha wasn’t a gift. It was a transaction, and you were the product.
The tell was right there on the model’s OpenRouter profile, in the kind of disclaimer everyone scrolls past: all prompts and completions were logged by the provider and could be used to improve the model. Read that again. A frontier-class, trillion-parameter model, served for free, hoovering up the single most valuable and hardest-to-synthesize dataset in AI right now: real, production-grade agentic execution traces. Actual multi-step plans. Actual tool calls. Actual self-correction loops from actual companies solving actual problems.
You cannot buy that data. You can barely fake it. And thousands of developers handed it over voluntarily, in exchange for a $0.00 invoice, to an anonymous provider they couldn’t identify until after they’d already routed their workloads through it.
This is the oldest play in the book — subsidize to commoditize, the move that built cloud infrastructure, ridesharing, and a dozen hardware empires — fused with a modern AI twist: the loss-leader isn’t buying market share, it’s buying your data and your ecosystem lock-in. Spend weeks tuning your agent stack to one model’s quirks, latency profile, and prompt idiosyncrasies, and the switching cost you’ve just built becomes the wall the provider rents you back to once the free tier ends.
For a general-purpose B2C startup, maybe that’s a risk you accept with eyes open. For your startup — and I’m going to assume the hardest version of the profile, because that’s the one worth designing for — it’s disqualifying.
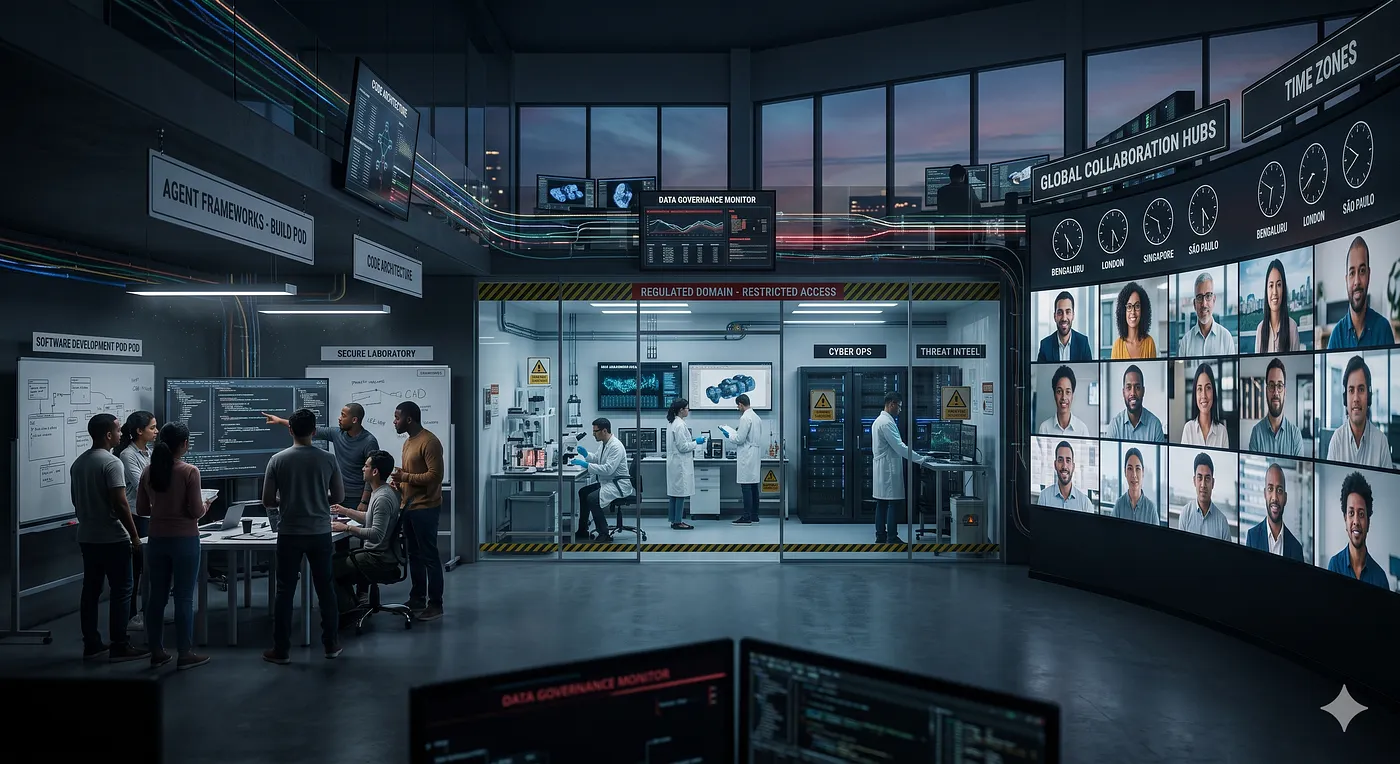
The Hypothetical AI Startup — Image by Gemini
Picture the team:
- Five to ten expert engineers building the agent frameworks
- Five to ten advanced researchers working in a regulated domain — biotech sequences, defensive cyber, hard-engineering IP
- Ten or more offshore collaborators and consultants distributed across time zones.
That topology is a gift for velocity and a minefield for data governance. And the moment any of that regulated data touches an unvetted third-party endpoint, you’ve created an exposure that no cost saving can offset.
Be concrete about the exposure, because vague hand-waving about “privacy” doesn’t move sophisticated founders:
- Jurisdictional capture. A prompt routed through a Chinese-provider API is processed under China’s National Intelligence Law. If that prompt carries proprietary code, regulated customer data, sequence data, or defense-adjacent material, your legal exposure isn’t theoretical — it’s structural, and it doesn’t care about your intentions.
- Procurement death. In healthcare (HIPAA), defense and CUI (CMMC, ITAR/EAR), payments (PCI-DSS), or any enterprise B2B sale with a serious security questionnaire, “we send data to a foreign-hosted endpoint via a public aggregator” is not a yellow flag. It’s an immediate, conversation-ending disqualifier. You will not get to the pricing page.
- The shadow-AI breach surface. Your distributed team will use whatever is fastest unless you give them something faster that’s also safe. An offshore consultant pasting a snippet of core IP into a free public model to debug it on a Tuesday afternoon is a breach you’ll find out about in the post-mortem.
When the US Navy banned a popular Chinese model over privacy concerns, the instructive part wasn’t the ban — it was the reporting that a defense contractor’s engineers had quietly tested the same model anyway, because the cost math was seductive and the governance was nobody’s job. That’s the failure mode. The market doesn’t wait for policy, and your own people won’t wait for your security review unless you’ve built the rails first.
So the surface lesson — “the cheap model won, go cheap” — is, for you, an invitation to build a product that can’t be sold to the customers you’re targeting. Cheap is not the same as free, and free is never free when you’re the dataset.
Here’s the reframe that turns all of this from a threat into your unfair advantage.
Part 3: The real prize is sovereignty, not arbitrage
The genuine, durable gift of the open-weight era to a regulated startup is not access to cheap foreign APIs. It’s that frontier-class capability is, for the first time, a thing you can own and host yourself.
Sit with the difference, because it’s the whole point.
Arbitrage is renting someone else’s intelligence because it’s cheap today. It’s reversible, it’s jurisdictionally exposed, and it’s at the mercy of a provider who can change the price, log the traffic, or pull the model. Sovereignty is running frontier-class open weights inside your own perimeter — your VPC, your tenant, your hardware. Same capability. Same dramatic economics, because the weights are open and the per-token cost collapses to your own compute. But the data never leaves, the jurisdiction is yours, and no one can switch you off.
And if you think “no one can switch you off” is a paranoid edge case, look at what happened in June 2026. Anthropic launched its top-tier Fable 5 and Mythos 5 models on June 9 — and suspended access on June 12 in response to a US government export-control directive. Three days. A frontier capability that real businesses had every reason to build on, available Monday, gone Thursday, by directive. Whatever you think of the policy, the operational lesson is brutal and non-partisan: if your product’s core intelligence is a hosted frontier API you don’t control, your business has a kill switch you don’t hold. It can be flipped by a regulator, a pricing committee, a geopolitical event, or a provider’s risk appetite, and your roadmap evaporates with it.
This is exactly where your “international team” and “residency” anxieties resolve into a clean architectural answer instead of a compliance dodge. You are not trying to beat a residency requirement, you are trying to make the residency question irrelevant, by adopting an architecture in which the sensitive intelligence runs on infrastructure you control, in a jurisdiction you choose. When the model runs in your tenant, “where does the data go?” has a one-word answer: nowhere. That answer is what passes audits. That answer is what your customers can pass to their customers. That answer is the moat.
The open-weight movement is what makes this newly affordable. A year ago, “self-host frontier capability” meant a research-lab budget. Today, a stack of strong open-weight models — the Qwen, DeepSeek-derived, and similar families — can be served at high throughput on infrastructure you rent or own, and the heavily-quantized variants run on a single high-memory workstation. The same efficiency obsession that made Chinese models cheap on public APIs — mixture-of-experts designs, aggressive quantization, NPU/iGPU hybrids on unified-memory hardware — is the efficiency that lets you run them in-house without a hyperscaler-sized bill.
So the move isn’t “route your regulated data through the cheapest foreign endpoint and hope.” The move is: take the economics the open-weight era unlocked, and capture them inside a perimeter you own. You get the velocity. You get the cost collapse. You get independence from any single vendor’s geography, pricing, or kill switch. And you get compliance not as a bolted-on policy but as a property of the architecture.
Now let’s make it operational, because a thesis without a blueprint is just a vibe.
Part 4: The three-tier compute blueprint
Stop looking for a single, company-wide AI policy. A 25-person team spanning core engineers, regulated researchers, and offshore consultants doesn’t have one data-risk profile; it has three. So build three tiers, segmented by the sensitivity of the data each group touches. Velocity comes from not forcing your engineers through the same heavyweight controls your researchers need, and safety comes from not letting your offshore contractors anywhere near the controls your engineers enjoy.
Tier 1 — The Core Research Vault (your regulated researchers)
The five-to-ten people handling biotech sequences, defensive cyber vectors, or proprietary engineering constraints need a zero-leakage perimeter. No exceptions, no “just this once.”
- Infrastructure: In-tenant cloud — a dedicated VPC on AWS Bedrock or Azure with explicit zero-data-retention clauses — or, where the regulatory bar is highest, a private on-premise GPU cluster. The data plane never traverses a public aggregator.
- Models: Top-tier open-weight models served inside that perimeter via a high-throughput engine like vLLM or TensorRT-LLM. You get frontier-adjacent capability with the weights sitting on disks you control.
- The economics: The lever founders miss — running open weights yourself puts per-token cost in cheap-public-API territory while keeping every byte inside the perimeter. On-prem is amortized capex: buy the GPUs once, marginal cost trends toward your power bill — best at steady volume. In-tenant VPC is rented compute with no capex, and it’s the bill hyperscaler startup credits can offset (below). Sovereignty at arbitrage prices.
Tier 2 — The Local Iteration Layer (your core engineers)
The engineers building the agent loops, tool-calling layers, and self-correction pipelines need raw speed and infinite reps. If they’re waiting on cloud latency and watching a meter tick for every local integration test, your velocity dies by a thousand small frictions.
- Infrastructure: High-memory local workstations, or a shared local lab server. The unified-memory class of machine — the kind that puts 128 GB behind an iGPU/NPU and runs a 70B-class model entirely on-device — is now a category, not a science project, and it’s purpose-built for exactly this. Apple’s Mac Studio, NVIDIA’s DGX Spark, and AMD’s Strix Halo all compete in this arena.
- Models: Heavily quantized open-weight models (4-bit/8-bit) served locally through Ollama or vLLM. An engineer debugging an agent framework does not need a trillion-parameter model; a sharp 8B–32B running locally gives them sub-second latency and free, unlimited test tokens.
- The payoff: Your team can run agent loops thousands of times a day for $0 of marginal cost and zero data exposure, iterating at a tempo a metered cloud API structurally cannot match. Velocity is the product here, and you’ve made it free.
Tier 3 — The Zero-Trust Gateway (your offshore collaborators and consultants)
The ten-plus distributed contributors are your biggest velocity multiplier and your biggest leak risk. You make trust unnecessary by removing every path around the chokepoint: contributors work inside a managed, ephemeral environment — a VDI or cloud dev workspace — whose only outbound AI route is the gateway. Nothing sensitive is checked out to a laptop you don’t control, and there’s no direct network path to any model API or vector store. The chokepoint isn’t a rule you ask them to follow; it’s the only door that exists.
- Infrastructure: A central, internal AI gateway or proxy that is the only path external contributors have to any model. Offshore developers never hold raw API keys to anything — not OpenAI, not Anthropic, not your internal clusters.
- Models: The gateway routes their requests to a sandboxed pool of open-weight models hosted on infrastructure you control.
- The controls that make it safe: Per-developer token quotas (a compromised laptop overseas can’t drain your budget), structured logging of every call, and automated scrubbing of secrets, credentials, and PII before anything is processed. The contributor gets fluid AI capability and ships features fast; the company never exposes a raw key or a piece of core IP to a device it doesn’t manage.
- The proprietary RAG (the part most teams get wrong): Reads run server-side — retrieval and generation happen inside the perimeter, scoped by per-collection ACLs, so only the answer leaves, never the corpus. Writes are governed like code review: contributions sit in a quarantined staging index and reach production only after a provenance, license, and PII check. Scanning writes is critical as an unvetted document is a poisoning vector that corrupts every downstream answer.
The connective tissue: never hardcode a provider
Above all three tiers sits the single most important architectural decision you’ll make: build an abstraction layer, and route by data-risk profile, not by habit.
The biggest unforced error in 2026 is hardwiring your application to one provider’s API. Build instead on an LLM gateway or a lightweight router that implements strict, structural tool-calling mapping across models. Then route deliberately:
- High-volume, non-sensitive utility work — parsing public web data, generating synthetic data, format-checking, broad summarization of non-confidential material — can flow to the cheapest adequate hosted model, through the gateway, with scrubbing. This is where the public-API cost advantage legitimately lives, and you should absolutely exploit it.
- Sensitive reasoning, regulated data, and anything touching core IP routes to your in-perimeter open-weight endpoints.
The strategic prize of the abstraction layer is independence. The winner in this era isn’t the team running the best model; it’s the team that can swap to whatever is cheapest, fastest, or most compliant tomorrow, at the gateway level, without rewriting a line of application code. When the next Hunter Alpha drops — and there will be a next one — you evaluate it in an afternoon, route a non-sensitive workload to it through the gateway, measure your own metrics, and either adopt or discard it. You are never locked in, because you never built a wall around yourself.
Part 5: The credit-arbitrage play (the legal version of “beating the system”)
Here’s the move that actually delivers the “low cost, high velocity, beat the system” energy — and it’s entirely above board.
Hyperscalers fall over themselves to hand startups $100,000–$200,000 in cloud credits. The credits are bait: they’re designed to lock you into the vendor’s proprietary, higher-margin managed services, so you spend it all on premium closed-API calls and wake up dependent.
Don’t take the bait. Take the credits.
Spend them not on premium managed APIs, but on raw compute — GPU instances you spin up yourself — and use that “free” infrastructure to self-host top-tier open-weight models via vLLM or Text Generation Inference. The outcome is the trifecta:
- You get open-ecosystem token economics — fractions of a cent where a premium API would charge dollars.
- You keep your data inside a US (or otherwise compliant) cloud perimeter, never touching a foreign-hosted endpoint or a public aggregator.
- The whole thing is funded by the vendor’s own credits.
You’ve used a hyperscaler’s growth-team budget to build a sovereign, compliant, frontier-capable inference stack that their own sales team would rather you didn’t. That’s the play. That’s how a lean regulated startup gets the cost structure of a commodity shop and the compliance posture of a defense contractor at the same time — and does it on someone else’s dime for the first year, exactly when runway matters most.
Part 6: Why this wins — velocity and independence, honestly earned
Step back and look at what this architecture buys you against the company that read the surface lesson and just wired itself to the cheapest public API.
Velocity. Your engineers iterate on local, quantized models with infinite free tokens and sub-second latency. Your gateway lets you adopt a new model in an afternoon instead of a rewrite. You move faster than the metered-API shop, not slower, because you’ve removed both the cost friction and the lock-in friction from your inner loop.
Independence. You own the weights for everything sensitive. No provider can price you out, log your traffic, or — as Fable and Mythos just demonstrated in 72 hours flat — have your core capability suspended by directive. When the geopolitical weather changes, and it will, your stack keeps running. You’ve converted “which model is allowed where this quarter” from an existential question into a routing config.
Compliance as architecture, not theater. “Nothing sensitive leaves our perimeter” isn’t a policy you hope your team follows; it’s a property your topology enforces. That’s the difference between a security questionnaire you survive and one you breeze through. And it’s a claim you can hand to your customers so they can make it to theirs — the same way a private-AI appliance company sells not just a tool but a promise its buyers can pass downstream.
Cost. Credits fund the build. Open weights and quantization gut the per-token bill. Local iteration is free at the margin. You arrive at commodity-shop economics without commodity-shop exposure.
Now the honest part, because a thesis that only flatters you is propaganda. This is real work — the gateway, the routing, the tiered perimeters, and a matched set of model versions that all actually work together — and it needs ongoing maintenance, because the next driver or model release will break something. But that upkeep is the moat, not a tax: it’s exactly what a competitor can’t clone by buying the same chip or calling the same API, and it’s bounded engineering, not a moonshot. The model was never the edge; the maintained, sovereign integration is. Build it before the category commoditizes and you own something the arbitrage crowd structurally can’t.
One tradeoff to name plainly: the absolute bleeding edge still lives behind a few premium hosted APIs. That’s fine — route the rare frontier-only task to a compliant, zero-data-retention endpoint and keep everything else sovereign. The tradeoff becomes a line in your routing config, not a ceiling on the business.
Part 7: The playbook
If you do nothing else, do these, roughly in order.
1. Audit your token spend. Pull the last 30 days of API logs. Compute cost-per-million-tokens per workload. If you’re running high-volume agentic tasks on premium APIs, you’re likely overpaying by a large multiple — and you now know exactly which workloads to move first.
2. Build the abstraction layer before you need it. Put a gateway/router between your application and every model. Make provider choice a config value, never a code dependency. This one decision is what makes everything else — multi-tier routing, painless model swaps, surviving the next access cutoff — possible.
3. Stand up the three tiers by data-risk profile. Vault for regulated researchers (in-tenant or on-prem, open weights via vLLM/TensorRT-LLM, ZDR). Local layer for engineers (quantized open weights on high-memory workstations). Zero-trust gateway for offshore contributors (no raw keys, quotas, logging, PII/secret scrubbing).
4. Claim the credits, spend them on raw compute. Take the hyperscaler startup credits. Don’t burn them on premium managed APIs — use them to self-host open weights inside your compliant perimeter.
5. Legal-gate every model you adopt. Open weights still carry licenses, and not all are cleared for commercial redistribution or for your specific data flows. Make a license and jurisdiction check a required gate before any model enters production. Prefer permissively-licensed weights. This is a five-minute habit that prevents a six-figure mistake.
6. Decide where cheap public APIs do belong — and wall them there. Non-sensitive, public-data, synthetic-generation, formatting work, routed through the gateway with scrubbing, is a legitimate and lucrative use of the cheap-model economics. Just keep regulated data and raw keys on the other side of the wall, permanently.
7. Treat the maintained stack as the moat. Budget for the ongoing work of keeping the matched set — kernels, drivers, runtimes, model versions — validated together. The integration that breaks if any piece moves is exactly the asset competitors underestimate.
The new map
The ghost wasn’t the story. Xiaomi’s free trillion-token campaign was a brilliant data-harvesting and ecosystem-capture play, and the developers who flooded it with production workloads were the raw material, not the beneficiaries. The token charts everyone screenshot were real, and the cost-per-task revolution underneath them is the genuine, permanent shift. But the conclusion the headlines want you to draw — the cheap model won, so rent the cheap model — is the one conclusion that, for a regulated, internationally-distributed startup, leads straight off a cliff.
The durable lesson is the opposite of arbitrage. The open-weight era didn’t just make intelligence cheap to rent; it made frontier-class intelligence cheap to own. For the first time, a lean team can hold the economics that made Chinese models unstoppable on public platforms and the data sovereignty that regulated customers demand and independence from any provider who can log, price, or — in 72 hours, by directive — switch off the capability your business depends on.
You don’t beat the residency requirement. You make it irrelevant, by running the intelligence on infrastructure you control, in a jurisdiction you chose, behind a perimeter your architecture enforces. That’s not the expensive option anymore. With open weights, quantization, a gateway, and a stack of cloud credits, it’s the cheap one and the compliant one and the fast one — at the same time.
The era of renting your intelligence from someone who can read your prompts, raise your rates, or pull your model overnight is ending. For everyone else it’s a convenience. For you, it’s existential. Own the weights, and the ghost stops being a cautionary tale and starts being a free lesson in exactly how the next decade gets won.
Build the perimeter. Take the credits. Own the stack. Then move fast — because now you can afford to, and no one can turn you off.