Silicon Valley spent twenty-five years training the public to expect a grift. Now that the industrial engine has actually arrived, our well-earned cynicism has become a fatal liability.
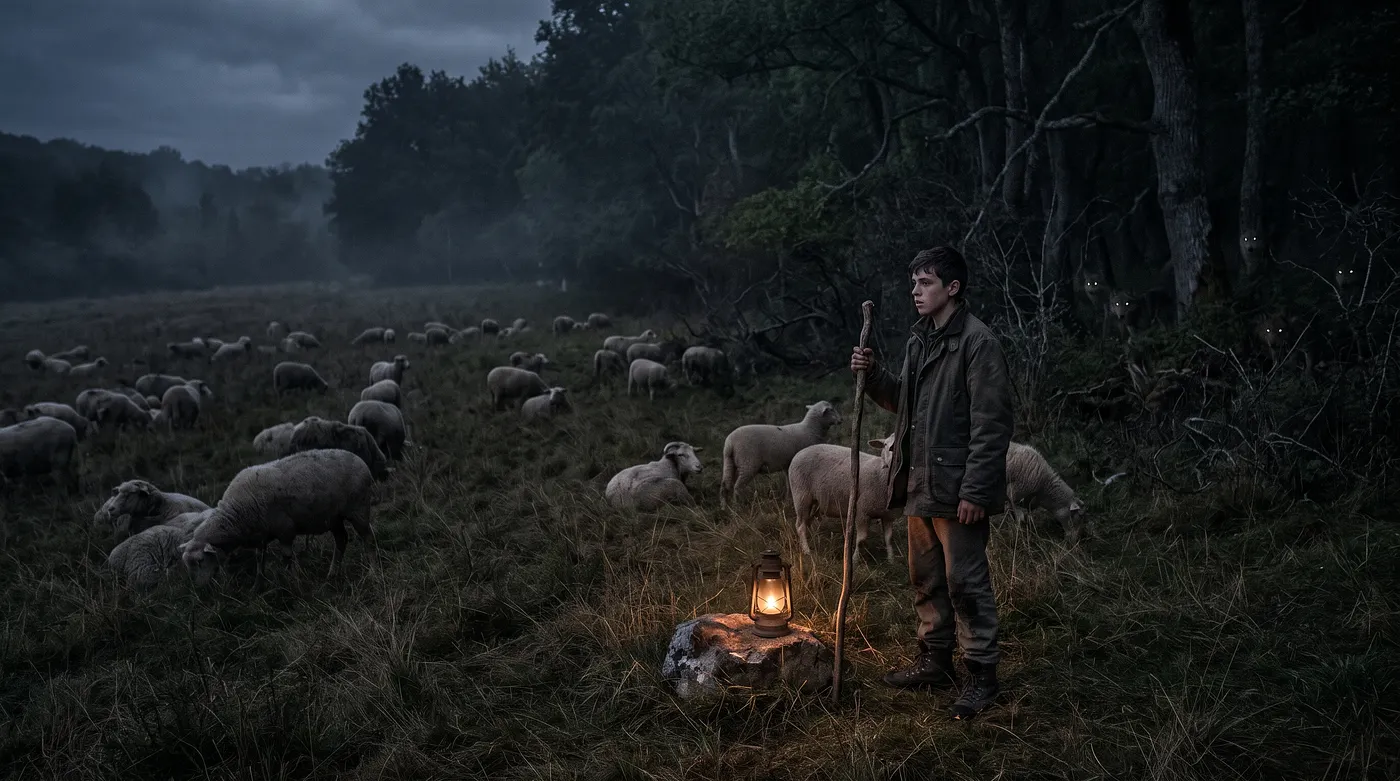
The Boy who cried Wolf is normally a fable about lying, it has another darker meaning — Image by Gemini (AI)
Oct. 26, 2026 — Madkat Omega
The Fourth Night in the Pasture
Picture the village tavern on the fourth night of Aesop’s fable. For three consecutive evenings, the shepherd boy stationed on the high pasture has blown his horn, summoning the townspeople up a steep, rocky trail with their pitchforks and lanterns, only to greet them with laughter and an empty meadow. By the fourth evening, the most seasoned tradespeople in the village have learned their lesson. When the horn echoes down from the ridge at dusk, nobody reaches for a coat. The blacksmith pours another mug of ale and explains to the younger apprentices how the boy manufactures panic to steal their evening rest. Around the hearth, the mood is warm, perceptive, and quietly triumphant. The villagers have seen through the manipulation. They have analyzed the historical data, recognized the pattern of deception, and refused to be played for fools a fourth time. Two miles up the ridge, in the gathering dark, a pack of grey timber wolves slips beneath the pasture fence and begins slaughtering the flock.
Every retelling of the fable treats it as a morality play about the boy’s dishonesty. We rarely examine the tragedy from the vantage point of the villagers sitting in the tavern. Their skepticism was empirically justified, grounded in three consecutive experiences of fraud, and fatally wrong.
In the autumn of 2026, a massive contingent of writers, commentators, software engineers, and everyday digital citizens has settled comfortably into that tavern. Across social platforms, video essays, and independent newsletters, a potent cultural consensus has hardened around a decisive verdict: AI is a scam. According to this burgeoning orthodoxy, generative artificial intelligence represents the final, desperate confidence trick of a stagnating American technology sector. When a frontier model hallucinates a legal citation, when an enterprise chatbot embarrasses an airline, or when a multibillion-dollar data center campus hits a permitting bottleneck in the desert, the tavern erupts in applause. Each stumble is cataloged as proof that the whole edifice is a mirage of circular venture financing and stolen art, destined to evaporate just like every other Silicon Valley fever dream of the past decade.
Control room engineers and site reliability architects have a clinical term for this behavioral trap: alert fatigue. When an poorly calibrated monitoring system floods an operations center with thousands of false-positive paging alerts over months of routine service, human operators adapt by muting the audio channels or writing automated rules to route the warnings straight to a trash folder. The human brain preserves its sanity by filtering out chronic noise. Yet the physics of the underlying machinery remain indifferent to the operator’s exhaustion. When a genuine cooling pump failure cascades through the primary reactor core, the muted console stays silent until the facility melts down.
Understanding why so many intelligent people have muted their consoles requires examining the deep psychological utility of the scam narrative. Declaring machine intelligence a hollow grift provides immediate emotional shelter. For two centuries, technological mechanization targeted human muscle, automating the loom, the assembly line, and the shipping yard while leaving white-collar cognitive work untouched at the top of the economic pyramid. Now, a class of software engineers, legal analysts, medical diagnosticians, and commercial illustrators confronts a computational architecture capable of parsing syntax, synthesizing unstructured archives, and drafting working code in seconds. Dismissing these systems as glorified autocomplete offers a powerful sedative against existential career dread. If the technology is fake, nobody needs to rethink their craft, rebuild their workflows, or confront the terrifying decoupling of human intelligence from economic scarcity.
This defensive reflex is compounded by the way the public encounters artificial intelligence in the wild. Very few citizens wake up in the morning and interact with a neural network folding novel proteins for oncology research or optimizing bare-metal robotics kinematics in a regional grocery distribution hub. Instead, the average internet user experiences machine intelligence as an aggressive degradation of the digital commons. They see search engine results choked with synthetic slop, social feeds flooded with grotesque automated imagery, customer support phone trees guarded by unhelpful bots, and corporate executives using vague automation promises to justify quarterly layoffs. Confronted with this daily friction, the public equates the sleazy monetization strategies of corporate middlemen with the capability of the underlying compute engine. They look at the carnival barker selling watered-down tonic out front and conclude that the industrial steam turbine roaring behind his tent must be made of cardboard.
How US Tech Burned Its Social Capital
Public hostility toward Silicon Valley did not emerge from irrational Luddism; it was forged through twenty-six years of broken social contracts. Since the turn of the millennium, the American technology industry has repeatedly wrapped speculative financial extraction in the language of human liberation. Tracing that lineage reveals why the public’s fraud detectors now fire automatically whenever a founder steps onto a stage in a leather jacket or a black turtleneck.
The erosion of trust began on the night of December 31, 1999. For three years leading up to the millennium, media outlets and government agencies warned that the Y2K bug would halt power grids, ground commercial aviation, and freeze banking systems. The underlying engineering flaw was real: in the 1960s and 1970s, when magnetic core memory cost dollars per byte and punched cards held exactly eighty columns, COBOL programmers encoded years using two digits to save precious storage space. Across the late 1990s, an army of systems engineers worked grueling shifts to audit and remediate hundreds of millions of lines of legacy mainframe code. Because those engineers succeeded, January 1, 2000 dawned without a single major infrastructure failure. To an uninformed public watching from the outside, the smooth rollover looked like proof that the technology industry had fabricated an apocalyptic crisis to bill billions of dollars in consulting fees.
Fifteen months later, the Dot-Com bubble burst across the NASDAQ, wiping out five trillion dollars in market value between March 2000 and October 2002. During the mania, Wall Street investment banks took unprofitable startups public on the promise that traditional balance sheets had been rendered obsolete by “eyeballs” and network effects. Simultaneously, telecommunications giants such as WorldCom and Global Crossing used fraudulent accounting and circular capacity swaps to disguise saturating demand while laying millions of miles of optical fiber. When the accounting imploded, retail investors saw their retirement accounts decimated while insiders walked away with fortunes.
The second act of disillusionment arrived packaged as community. Around 2005, the Web 2.0 movement promised to replace corporate media gatekeepers with participatory town squares. Early platforms invited users to share photographs, maintain blogs, and connect with childhood friends for free. Within a decade, the architecture of those platforms shifted from chronological connection to algorithmic enclosure. Engineers realized that human attention stayed glued to screens longest when fed a steady diet of moral outrage and tribal polarization. By harvesting behavioral telemetry and auctioning micro-targeted influence to advertisers, social media monopolies turned the public commons into an extraction engine while devastating local journalism and civic trust.
During the zero-interest-rate decade of the 2010s, the extraction model moved from digital screens into physical labor through the gig economy. Venture capital firms poured tens of billions of dollars into rideshare, food delivery, and coworking conglomerates. The consumer experience during the subsidy phase felt magical: a private car across town cost less than a subway ticket, and restaurant meals arrived at the door with zero delivery fees. Once that predatory pricing bankrupted traditional taxi fleets and forced local restaurants into platform dependency, the subsidies vanished. Fares tripled, restaurants surrendered thirty percent of their gross margins, and full-time drivers found themselves classified as independent contractors stripped of healthcare, overtime protections, and predictable wages. Consumers learned a hard structural lesson: Silicon Valley convenience is a temporary loss-leader designed to establish a tollbooth.
The fatal blow to tech credibility arrived between 2017 and 2022 with the rise of cryptocurrency, Web3, and non-fungible tokens (NFTs). Technically, a public proof-of-work blockchain is an append-only distributed database that intentionally sacrifices throughput and energy efficiency to achieve consensus without a central administrator. Bitcoin processes roughly seven transactions per second globally; Ethereum’s base layer handled roughly fifteen during the height of the mania. Yet venture capitalists, celebrity endorsers, and tech executives marketed this slow, high-friction ledger as the imminent replacement for global banking, property deeds, medical records, and software architecture.
Billions of dollars flowed into speculative tokens backed by wash trading, algorithmic stablecoins that mathematically guaranteed their own death spirals, and digital receipts pointing to cartoon monkey images hosted on centralized web servers. When Terra-Luna, Celsius, and FTX collapsed in rapid succession throughout 2022, millions of ordinary people realized that the technology industry had shed even the pretense of building useful tools. It had become an unregulated casino where insiders dumped worthless digital chips onto retail buyers.
Then, in November 2022, the casino lights flickered, and the exact same venture capital firms, LinkedIn thought leaders, and conference keynote speakers pivoted overnight from Web3 to generative artificial intelligence. They deployed the exact same breathless vocabulary. They warned once again that anyone who failed to buy in immediately would be left behind by history. To a bruised and exhausted public, the conclusion was obvious: the grifters had simply changed costumes.
The Anatomy of a Category Error
Equating artificial intelligence with cryptocurrency because both attracted venture capital hype commits a fatal category error. Compare a plastic casino chip to a commercial refrigeration compressor. A casino chip possesses value only as long as the house stays solvent and the players inside the room agree to honor the plastic disk; the moment confidence evaporates, the disk becomes landfill clutter. A refrigeration compressor pumps refrigerant through a condenser coil to extract heat from an insulated cabinet. It keeps meat and medicine from spoiling at forty degrees Fahrenheit whether Wall Street investors are manic, depressed, or bankrupt. Cryptocurrency was a casino chip searching desperately for an economic justification. Machine intelligence is a thermodynamic compressor for cognitive work.
To understand whyWeb3 produced nothing while artificial intelligence is rewiring global industry, one must look at the first fifteen minutes of user interaction. Adopting a Web3 application required reading a ten-page ideological manifesto on monetary decentralization, installing a browser wallet extension, writing a twelve-word cryptographic seed phrase on a slip of paper, purchasing volatile tokens on an offshore exchange, and paying twenty dollars in network gas fees just to sign into a ghost-town application that ran slower than a 1998 web forum.
When large language models reached the public, they required zero ideological conversion. A high school teacher pasted a chaotic lesson plan into a text box and received a structured rubric in four seconds. A systems administrator pasted a cryptic three-hundred-line Linux kernel panic log and received the exact misconfigured driver flag. A paralegal uploaded a two-hundred-page commercial lease and extracted every indemnification clause before their coffee cooled. The utility was immediate, self-evident, and independent of token prices.
The mechanical breakthrough driving this utility dates back to a 2017 research paper published by eight Google engineers titled “Attention Is All You Need.” Prior to the Transformer architecture introduced in that paper, machine learning models processed sequential data (like sentences or lines of code) word by word through recurrent neural networks. By the time an older model reached the end of a long paragraph, the mathematical signal from the opening sentence had degraded, much like a message whispered down a long line of people. Furthermore, traditional software engineering has always relied on deterministic, human-authored rules: an engineer anticipates every possible input and writes explicit conditional branches to handle them. Whenever the real world presents an unscripted edge case, traditional software crashes or halts.
The Transformer architecture solved both constraints through a mathematical mechanism called self-attention. Instead of reading sequentially, a Transformer ingests an entire block of tokens simultaneously (whether those tokens represent English prose, C++ syntax, warehouse floor coordinates, or amino acid chains) and computes an attention matrix that weighs the contextual relationship between every single element and every other element in parallel. By mapping these high-dimensional statistical relationships across massive datasets on parallel graphics processing units, the model builds an internal geometric representation of how systems behave.
While internet commentators spend their days mocking consumer chatbots for failing riddles about how many letter R’s appear in the word strawberry, this underlying computational engine has quietly embedded itself into the foundational plumbing of the physical and digital economy across four distinct domains:
Autonomous Industrial and Supply Chain Robotics
Step inside a modern automated grocery distribution center in 2026. For decades, industrial automation meant bolting a blind mechanical arm to a concrete floor inside a safety cage and programming it to repeat the exact same weld at the exact same millimeter coordinate ten thousand times a day. If a cardboard case of cereal arrived crushed by half an inch, or if condensation made a shrink-wrapped pallet slip, the line jammed and waited for a human technician. Today, fleets of autonomous mobile robots orchestrated by bare-metal Kubernetes clusters navigate high-density storage structures at high speeds. Multi-modal vision and kinematics models process real-time LiDAR and camera telemetry at the edge, calculating center-of-gravity shifts, adjusting grip pressure on deformable packaging, routing around unexpected physical obstructions, and recalculating fleet-wide fault recovery in milliseconds. This is physical intelligence moving millions of tons of food from farm to shelf.
Legacy Codebase Remediation and Structural Maintenance
Much of the modern world’s banking, healthcare claims processing, municipal tax collection, and small-business publishing runs on brittle legacy codebases written twenty to forty years ago in COBOL, Fortran, and early PHP. For decades, institutions left these systems untouched in a state of terrified stasis because the original authors had retired and the cost of hiring human engineers to untangle millions of lines of undocumented spaghetti logic exceeded the annual IT budget. In 2026, autonomous engineering agents ingest entire legacy repositories across million-token context windows. They map hidden dependency graphs, generate comprehensive regression test suites that verify exact behavioral parity, refactor memory-unsafe routines into modern compiled languages, and deploy automated security patches through GitOps pipelines. Years of latent technical debt are being excavated in weeks.
Biological Discovery and Materials Science
In traditional pharmaceutical and materials engineering, determining the three-dimensional shape of a single protein from its one-dimensional string of amino acids required months or years of painstaking X-ray crystallography in a laboratory at a cost of hundreds of thousands of dollars per structure. Google DeepMind’s AlphaFold systems predicted the 3D structures of over two hundred million known proteins — virtually every protein cataloged by science — and released the database to the global research commons. In 2026, generative molecular diffusion models design custom enzymes from scratch to break down industrial plastics, model candidate compounds for antibiotic-resistant bacteria, and simulate solid-state battery electrolytes before a single chemical is mixed in a wet lab.
Local Sovereign Compute
Perhaps the most decisive rebuttal to the corporate enclosure narrative is happening on the desks of independent builders. Critics frequently claim that artificial intelligence is merely a plot to trap humanity inside recurring twenty-dollar-a-month cloud subscriptions owned by five coastal monopolies. That critique ignores the explosion of highly capable open-weights models — such as the Qwen, Gemma, and DeepSeek families — combined with workstation-class unified memory architectures. Using compact desktop hardware equipped with high-bandwidth unified system memory, an independent engineer, medical clinic, or local law firm can download a quantized seventy-billion-parameter reasoning model and run it entirely offline on bare metal. Once the weights reside on a local NVMe drive, no corporation can censor the model, hike the subscription fee, harvest the user’s private documents, or revoke access. The printing press has escaped the monastery.
Why the Financial Bubble Will Burst and the Engine Will Remain
At this point in the argument, the tavern skeptic usually plays their trump card: the balance sheet. They point to astronomical price-to-earnings multiples on semiconductor stocks, circular investment deals where cloud providers give startups compute credits that are immediately booked back as cloud revenue, and a sprawling ecosystem of venture-backed wrapper companies charging enterprise fees for thin user interfaces bolted onto someone else’s API. Surely, the skeptic argues, when this financial bubble pops, the entire AI mirage will vanish with it.
The skeptic is completely right about the financial bubble, and completely wrong about what happens the morning after it bursts.
In 2002, the Venezuelan-British economist Carlota Perez published Technological Revolutions and Financial Capital, a landmark historical study examining five centuries of industrial paradigm shifts. Perez demonstrated that every genuine general-purpose technology follows a violent, predictable two-stage rhythm: the Installation Period and the Deployment Period, separated by a sharp financial crash.
When a transformational technology first emerges, existing industries are not structured to absorb it, and nobody knows which business models will ultimately prevail. Consequently, financial capital takes the wheel. Driven by fear of missing out and the lure of monopoly windfalls, speculators flood the zone with cheap liquidity. This mania triggers a frantic, irrational overbuild of physical infrastructure. Eventually, investors realize that current revenues cannot service the mountains of speculative capital deployed, triggering a dramatic market crash.
Crucially, Perez showed that the crash never destroys the technology. Instead, the crash flushes out the financial speculators, writes down the capital debt, and hands the newly constructed physical infrastructure over to productive engineers and everyday businesses at pennies on the dollar.
History offers two crystal-clear blueprints of this mechanism in action:
The British Railway Mania of the 1840s
Following the success of the Liverpool and Manchester Railway in 1830, speculative fever gripped Victorian Britain. Between 1844 and 1846, Parliament authorized more than 270 separate railway acts totaling nearly ten thousand miles of new track. Promoters launched duplicative lines between small market towns, fraudulent surveyors sketched routes across impassable marshes, and middle-class families poured their life savings into railway scrip. At the peak in 1846, railway investment absorbed nearly seven percent of Britain’s entire gross domestic product. When the Bank of England raised interest rates in 1847, the bubble imploded. Railway shares plunged by more than fifty percent, speculators were ruined, and dozens of joint-stock railway companies collapsed into receivership. Yet the morning after the crash, nobody went out into the English countryside and ripped up the iron rails. The stone viaducts across valleys, the tunnels bored through hills, and the six thousand miles of steel track remained permanently on the ground. That overbuilt network dropped the cost of moving coal, iron ore, and agricultural goods by eighty percent, powering the Golden Age of Victorian industrial dominance.
The Telecom Dark Fiber Glut of 2001
Following the Telecommunications Act of 1996 and breakthroughs in dense wavelength-division multiplexing (which allowed a single strand of glass fiber to carry dozens of distinct laser wavelengths simultaneously), telecom carriers went on a debt-fueled construction binge. They tore up city streets and dragged submarine cables across ocean floors, laying over eighty million miles of optical fiber across the United States by 2001. When the telecom crash hit, roughly eighty-five to ninety percent of that buried glass sat completely unlit (“dark fiber”), and companies like Global Crossing filed for the largest bankruptcies in American history up to that date. Skeptics in 2002 mocked those buried conduits as monuments to Dot-Com stupidity. Four years later, YouTube, Netflix streaming, Amazon Web Services, and the global smartphone ecosystem materialized almost frictionlessly because bankruptcy courts had liquidated that transcontinental fiber network at ten cents on the dollar.
Now examine the capital expenditures of the 2026 artificial intelligence boom through Perez’s lens. Where did the capital go during the 2021 NFT bubble? It went into secondary wallet transfers, stadium naming rights, and offshore Bahamas real estate; when the music stopped, nothing physical remained. Where are the hundreds of billions of dollars in 2026 AI capital expenditures going? They are buying copper busbars, high-voltage step-down transformers, liquid-to-liquid cooling manifolds, custom photolithography silicon, and gigawatt-scale power generation.
Consider a concrete flashpoint from October 2026 that sent the doomer commentariat into a frenzy. When construction on Project Jupiter — a massive 2.45-gigawatt artificial intelligence data center campus in Doña Ana County, New Mexico backed by infrastructure financiers and anchor cloud tenants — encountered a force majeure notice alongside permitting battles over a dedicated natural gas pipeline and hundreds of megawatts of solid-oxide fuel cells, viral bloggers immediately declared that the AI bubble was imploding from collapsing demand.
They read the engineering blueprint upside down. A 2.45-gigawatt campus draws more continuous electrical power than the entire residential grid of several mid-sized American cities combined, exceeding the output of two full-scale nuclear reactors. The friction in southern New Mexico had nothing to do with vanishing software demand; it stemmed from the sheer physical violence of trying to weld high-pressure gas pipelines, permit industrial air-quality emissions, and manufacture solid-oxide fuel cells fast enough to feed an unprecedented industrial appetite for compute. Across the country, hyper-scalers are signing twenty-year power purchase agreements to restart dormant nuclear reactors like Three Mile Island Unit 1, funding small modular reactor designs, and rebuilding regional transmission interconnects.
Sometime between late 2026 and 2028, the equity market will almost certainly undergo a brutal Perez correction. Hundreds of thin software wrapper startups with no defensible moat will go to zero. Hardware stock multiples will compress when supply finally catches up to emergency procurement orders. The tavern skeptics will pop champagne, screenshot stock charts, and write triumphant victory laps proclaiming that they warned us all along. And while they celebrate a routine financial repricing, the freshly built substations, the restarted nuclear plants, and millions of interconnected tensor processors will keep humming, dropping the cost of machine intelligence by another two orders of magnitude and kicking off the true Deployment Age.
The Five-Year Horizon (2026–2031)
If a financial correction is harmless to the underlying engine, why does public belief in the “AI is a scam” narrative matter? It matters because time during an infrastructure transition is asymmetrical. A person who dismissed NFTs in 2021 lost nothing and saved their money. A person, enterprise, or municipality that dismisses artificial intelligence between 2026 and 2031 forfeits five years of compounding architectural adaptation.
When skeptics evaluate machine intelligence today, they commit the error of static snapshot analysis. They judge the permanent ceiling of the technology by the quirks of a consumer web interface in 2026, akin to examining a 1995 dial-up modem struggling to load a progressive JPEG image and concluding that the internet could never support live high-definition television or global financial settlement. Over the next sixty months, three structural shifts already operating in production environments will move from early adoption to baseline economic reality:
From Conversational Chatbots to Asynchronous Agentic Fabrics
The browser-based chat box — where a human types a prompt, waits ten seconds, and reads a paragraph of text — is a transitional user interface, much like the MS-DOS command line of the early 1980s. Between 2026 and 2031, the primary mode of machine intelligence shifts from synchronous conversation to asynchronous multi-agent execution.
In an agentic architecture, models do not sit idle waiting for a human to ask a question. Instead, specialized, bounded models are wired directly into an organization’s event streams, version-control repositories, telemetry buses, and hardware controllers. When a security vulnerability is disclosed in an upstream software library at three in the morning, an orchestrator agent wakes up, spins up an isolated sandbox container, locates every internal service utilizing the vulnerable function, rewrites the affected module, executes forty thousand integration tests to verify that latency and output remain unchanged, cryptographically signs the build artifact, and opens a verified pull request for human architectural review before the engineering team arrives at nine o’clock. Work stops being a sequence of manual keystrokes and becomes the supervision of autonomous operational loops.
The Evaporation of Cognitive Intermediaries
For the past half-century, modern corporations and government bureaucracies have scaled by adding layers of human translation. Because databases could not talk directly to legal contracts, and customer feedback forms could not talk directly to software compilers, organizations hired millions of middle-tier knowledge workers to act as human APIs. Their daily labor consisted of reading information in Format A (a regulatory PDF, a recorded sales call, a chaotic spreadsheet) and manually re-encoding it into Format B (a compliance checklist, a Jira ticket, an executive slide deck, a boilerplate CRUD database query).
As context windows stabilize in the millions of tokens and inference accuracy is reinforced through formal verification compilers and retrieval-augmented grounding, the friction that justified human API layers dissolves. Over the next five years, workflows that previously required a six-person committee three weeks of calendar time to coordinate will be executed continuously by underlying system plumbing. Workers whose professional identity rests entirely on translating unstructured text from one corporate silo to another without adding original structural judgment face a relentless compression of demand.
The Great Divergence in Human Agency
This brings us to the sharpest danger of the scam narrative: how it divides the workforce against its own interests. Consider two systems engineers, two independent journalists, or two small-business operators standing in October 2026.
The first professional has absorbed the tavern consensus. Convinced that large language models are unethical plagiarism engines and venture-capital vaporware that will vanish as soon as the bubble pops, they refuse to integrate local or frontier models into their craft. They wear manual execution as a badge of moral purity, spending thirty-five hours a week writing repetitive boilerplate configurations, manually cross-referencing legacy documentation, and fighting fires in reactive triage.
The second professional harbors zero illusions about Silicon Valley’s billionaire class, yet recognizes the raw mechanical leverage of the transformer engine. They deploy sovereign open-weights models on local hardware and wire agentic pipelines into their daily workflow. By automating eighty percent of their rote administrative and syntactic drudgery — the endless latent backlog of maintenance that used to consume their nights and weekends — they compress a week of mechanical execution into four hours on Monday morning. They reinvest the reclaimed thirty-six hours into deep systems architecture, physical hardware reliability, face-to-face human negotiations, and building resilient local networks.
By 2031, the gap between these two individuals will not be a marginal ten percent difference in productivity. It will be an unbridgeable gulf in operational scale. A single architect wielding an autonomous verification fabric will maintain infrastructure footprints that previously required a thirty-person department. Ironically, by boycotting the technology out of anti-corporate skepticism, the purist leaves the field completely uncontested for the most ruthless corporate actors while surrendering their own economic leverage.
On a macro scale, the societal cost of the scam narrative is even more severe. When labor unions, educators, and municipal policymakers convince themselves that artificial intelligence is a passing fad like 3D televisions or the Metaverse, they treat governance as a waiting game. Why overhaul vocational curricula, why modernize grid interconnection permitting, why fund public-compute commons, and why build portable safety nets for displaced cognitive workers if the bubble is going to burst and return the world to 2019? By the time the tavern doors are blown off their hinges around 2029, institutions that slept through the installation phase will find themselves trying to draft nineteenth-century rules for a twenty-first-century industrial reality.
An Architect’s Posture for the Deployment Age
Stepping out of the tavern does not mean kneeling before Silicon Valley’s altar. An honest systems architect can hold two truths in working memory at the same time: the financial markets surrounding artificial intelligence are saturated with carnivalesque hype, circular accounting, and predatory rent-seeking; and the underlying computational architecture is the most consequential general-purpose engine humanity has constructed since the electrical grid and the transistor.
Resisting the genuine abuses of the technology industry requires engaging with the machinery on concrete engineering terms rather than retreating into comforting denial. If we object to cloud monopolies enclosing human knowledge behind metered paywalls, the structural response is championing open-weights models, building local sovereign workstation infrastructure, and supporting open datasets as a protected public commons. If we object to corporations using premature automation to degrade service quality and strip-mine their workforces, the structural response is demonstrating how autonomous toolchains allow smaller, human-centered teams and one-person enterprises to outmaneuver bloated conglomerates on quality, speed, and trust.
Every great technological transition presents society with a choice between passive displacement and reclaimed agency. When electrical dynamos replaced the central factory steam shaft in the early twentieth century, manufacturers who simply swapped a steam engine for an electric motor in the basement saw almost zero productivity gains for twenty years. The breakthrough belonged to the architects who realized that small electric unit drives allowed them to tear down the dark, multi-story brick factories altogether and redesign manufacturing on bright, horizontal, single-story assembly floors where human workers had space to operate safely and efficiently.
The wolves are already in the upper pasture. They do not care that the shepherd boy lied about Web3 in 2021, they do not care that he lied about the gig economy in 2015, and they do not care whether NASDAQ software multiples drop by forty percent next spring. The compute substations are energized, the silicon is etched, and the compounding loops of cognitive automation are running twenty-four hours a day. Put down the ale, leave the warm comfort of the cynics’ table, and pick up the tools required to build the next floor.
References & Further Reading
Economic History & Infrastructure Cycles
- Carlota Perez, “Technological Revolutions and Financial Capital: The Dynamics of Bubbles and Golden Ages”
- Gareth Campbell, “Myopic Rationality in the British Railway Mania of 1845–1847”
- Federal Communications Commission, “High-Speed Services for Internet Access: Status of the 2001 Fiber Deployment”
Foundational AI Architecture & Empirical Benchmarks
- Ashish Vaswani et al., “Attention Is All You Need” (Advances in Neural Information Processing Systems, 2017)
- Josh Abramson et al. / Google DeepMind, “Accurate Structure Prediction of Biomolecular Interactions with AlphaFold 3” (Nature, 2024)
- Stanford Institute for Human-Centered Artificial Intelligence, “Artificial Intelligence Index Report”
Energy, Grid Logistics & Sovereign Compute
- International Energy Agency, “Electricity 2026: Analysis and Forecast to 2028 — Data Centres and AI”
- U.S. Department of Energy, “Recommendations on Powering Artificial Intelligence and Data Center Infrastructure”
- Constellation Energy, “Constellation to Launch Crane Clean Energy Center, Restoring Jobs and Carbon-Free Power to The Grid”