Before data centers, AI researchers had to ask what a mind is made of. Their answers explain where today’s chatbots keep breaking.
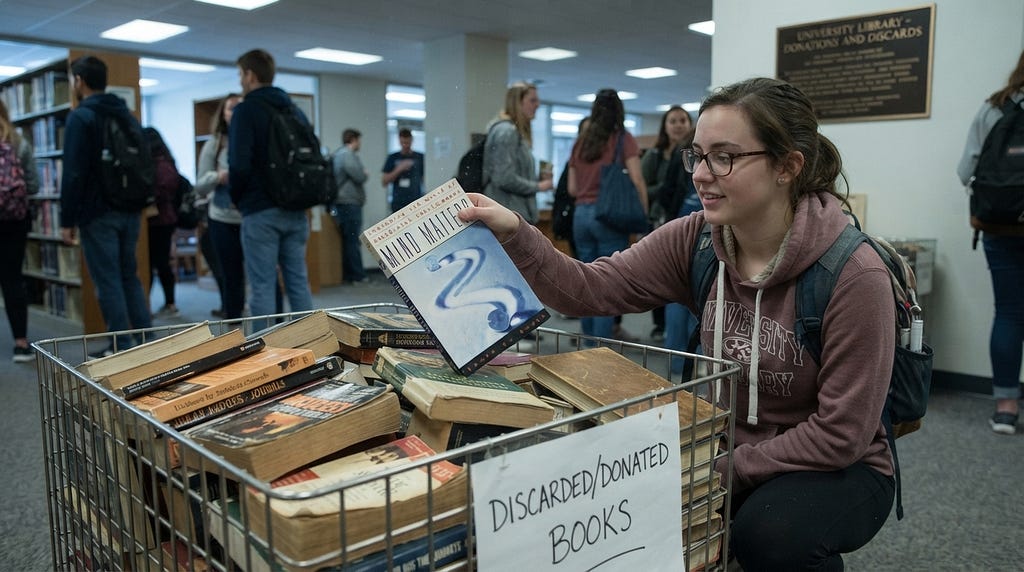
Image by Nano-Banana AI
Oct 19, 2026 · Madkat Omega
Ten years ago, I pulled a hardcover copy of James P. Hogan’s Mind Matters: Exploring the World of Artificial Intelligence out of a university library discard bin. Hogan was a British science fiction novelist who had trained as an engineer and spent years selling computer systems for Honeywell before he wrote full time. His book, copyrighted in 1997 and published by Del Rey the following spring, set out to survey the entire project of building a thinking machine.
Reading it to understand modern artificial intelligence sounds a little like studying a steam locomotive manual to fix a Tesla. When Hogan was writing, home internet connections crawled through telephone lines, IBM’s Deep Blue had just beaten Garry Kasparov at chess, and a computer that could hold a conversation in plain English belonged to fiction.
Today almost anyone can open a browser tab and type a question into ChatGPT. It drafts polite emails to difficult bosses, invents bedtime stories in seconds, and summarizes a fifty-page PDF before the coffee finishes brewing. For the first twenty minutes, it feels like talking to a mind.
Then the illusion cracks. A sideways riddle earns a nonsensical answer delivered with the confidence of a game show host. A request for five books on a niche historical topic returns titles nobody ever wrote. Through much of 2024, some of the most celebrated chatbots in the world insisted that the word “strawberry” contains two r’s, a failure so common that researchers at the University of Southern California wrote a paper investigating why systems fluent in mathematics and code could not count letters.
The yellowed pages of Mind Matters show that this blind spot was visible decades earlier. Hogan’s survey runs from the cybernetics experiments of the 1940s, through the robots being built at Carnegie Mellon and MIT, to Deep Blue and early attempts to recreate the evolution of intelligence in software. He gave real space to critics such as the physicist Roger Penrose, who argued that human understanding could never be reduced to computation, and to a problem that troubled every researcher of the era: how hard it is to give a machine the common sense behind ordinary English words.
Those researchers could not feed the entire internet into a data center, so they had to think carefully about what a mind actually is.
Those researchers could not feed the entire internet into a data center, so they had to think carefully about what a mind actually is. The industry that followed found a way around their questions. In the rush to build chatbots that sound human, it set aside five lessons that Hogan’s generation took for granted, and the limits of that shortcut are now plain to see.
The Dictionary in a Windowless Room
To see the first thing modern AI set aside, it helps to look at how a chatbot produces an answer. It does not know facts the way you know your mother’s birthday or the smell of rain on hot pavement. It is the most sophisticated autocomplete ever built. After training on billions of web pages, books, and forum arguments, the model calculates which word, or fragment of a word, most likely comes next. Type “peanut butter and,” and the system does not picture a sandwich. It has simply learned that “jelly” follows that phrase far more often than “carburetor.”
In 1990, Stevan Harnad, a cognitive scientist then at Princeton, gave the weakness of this approach a name: the symbol grounding problem. He asked how the symbols inside a machine could ever carry meaning of their own, instead of borrowing it from the people who read the output. His illustration was a learner trying to master Chinese with nothing but a Chinese-to-Chinese dictionary. It extended an older thought experiment from the philosopher John Searle, who in 1980 imagined himself sealed in a room, answering questions in Chinese by following a rulebook, producing convincing replies without understanding a word.
Picture yourself in that windowless room with a dictionary for a language you have never seen, where every word is defined only by other words in the same language. After a few years, patterns emerge. The squiggle for apple keeps appearing beside the squiggles for red, tree, sweet, and pie. When someone slides a question under the door, you can assemble a reply convincing enough that the person outside would swear you were fluent. You would still have no idea what an apple is. You have never felt its weight in your palm or heard its skin snap under your teeth. Every symbol in your head points only to other symbols, in a closed loop of definitions.
A language model lives in that room. It knows that “heavy” travels with “bowling ball,” “lead,” and “strain,” and rarely with “feather,” and it can write a moving paragraph about a character straining to lift a box. It has no muscles and has never pushed against gravity. Because we meet these systems through text, our own brains supply the missing experience. When the machine writes “pain” or “cold,” we fill in the sensation from memory and credit the machine with understanding.
Every symbol in your head points only to other symbols, in a closed loop of definitions.
The gap shows the moment software has to act in the physical world. Hans Moravec, a roboticist at Carnegie Mellon, observed in his 1988 book Mind Children that it was comparatively easy to make computers perform like adults on intelligence tests or at checkers, and extremely hard to give them the perception and mobility of a one-year-old. Rodney Brooks, who ran a mobile robotics group at MIT and later cofounded iRobot, turned that observation into a research program. His 1990 paper, “Elephants Don’t Play Chess,” argued that a robot’s abstract reasoning has to rest on direct sensory and motor contact with its surroundings. In 1993 his lab began building Cog, an upper-torso humanoid robot meant to learn about the world by acting in it. Humanoid projects like Cog mark the frontier where Hogan’s survey ends.
The field is now circling back to that frontier. In March 2025, Google DeepMind introduced Gemini Robotics, a vision-language-action model that adds physical movement as a new kind of output to its Gemini language model, so a robot can follow an everyday spoken request to fold origami or pack a snack into a zip-top bag. Later that year, Yann LeCun, a Turing Award winner who had spent twelve years as Meta’s chief AI scientist, left the company to found AMI Labs in Paris, which builds models that learn from real-world sensor data instead of text. In March 2026 the startup raised about $1 billion. Both efforts rest on the conviction Brooks defended in 1990: common sense has to be built from the bottom up, through contact with the world, before the words can mean anything.
The Flock and the Power Plant
Ask a chatbot how to lift a red wine stain from a cotton shirt, and the answer arrives so smoothly that the whole exchange feels weightless. The industry encourages that impression with a soft phrase, “the cloud,” as though artificial intelligence floated somewhere overhead like vapor. Behind the blinking cursor sits some of the heaviest industrial machinery on Earth.
For most of the past decade, the leading AI labs have improved their chatbots with one blunt strategy. When a model hits a wall, they make it bigger. They fill warehouse-sized buildings with racks of specialized chips, pump water through cooling systems to keep the silicon from overheating, and feed the result trillions of words scraped from every corner of the internet. The International Energy Agency projected in April 2025 that electricity demand from data centers worldwide will more than double by 2030, to about 945 terawatt-hours a year, slightly more than all of Japan consumes today. Tech companies are now shopping for power plants. In September 2024, Microsoft signed a twenty-year agreement to buy the full output of a reactor at Three Mile Island, which Constellation Energy plans to restart after five years offline.
Now consider the organ that sits behind your forehead. It can navigate a crowded grocery store, catch a baseball, recognize a friend’s laugh after twenty years, and invent a joke, all on roughly twenty watts, a fraction of what an old-fashioned household light bulb drew. A turkey sandwich and a glass of water keep it running.
The researchers Hogan wrote about were fascinated by how nature gets so much behavior from so little. Their answer was emergence, the idea that complex patterns can arise from many simple parts following local rules, with no central controller directing the whole. A flock of starlings twisting across an autumn sky like a single ribbon is the classic example. In 1987, the computer graphics researcher Craig Reynolds showed that he could reproduce that motion in software with three rules for each simulated bird. Steer to avoid crowding your neighbors. Match their average heading. Drift toward their average position. He called his creatures boids, and their flocks wheeled and split around obstacles with no leader and no master plan.
Twenty years later, a team of physicists centered in Rome checked the idea against real birds. By photographing starling flocks of a few thousand members from several angles and reconstructing each bird’s position in three dimensions, they found that every starling tracks, on average, just six or seven of its nearest neighbors, however far away those neighbors happen to be. Their 2008 study in the Proceedings of the National Academy of Sciences argued that this small, fixed circle of attention is what keeps a flock together when a hawk dives through it.
A modern AI lab asked to build that flock might start with a supercomputer on the ground, tracking the wind speed, position, and wing angle of every bird at once and radioing a fresh flight plan to each of them a thousand times a second. Nature spends almost nothing. Each bird watches a handful of neighbors, and the choreography takes care of itself. In the 1990s, when processors were slow and memory was expensive, AI researchers had no choice but to hunt for that kind of economy. They studied artificial life, evolving software, and small cooperating programs, looking for the mental equivalent of Reynolds’s three rules.
Each bird watches a handful of neighbors, and the choreography takes care of itself.
Then chips got cheap, investment flooded in, and size became the strategy. Training one enormous, uniform network on more data and more electricity reliably made a chatbot more fluent, so the search for elegant rules fell out of fashion. That road is running short. Researchers at Epoch AI, a group that tracks the inputs to AI development, estimate the usable stock of public human-written text at roughly 300 trillion tokens, the word fragments these models read, and expect it to be fully used up sometime between 2026 and 2032. In December 2024, Ilya Sutskever, a cofounder and former chief scientist of OpenAI, told the field’s largest research conference that “pre-training as we know it will unquestionably end,” because there is only one internet to learn from. He went on to point out that evolution once found a new way to scale intelligence in the brains of our human ancestors, and suggested that AI may need to find a different path of its own. If the next generation of AI is going to run without a dedicated power plant, it will have to learn what the starlings already know about building large behavior out of small, cheap parts.
The Improv Actor and the Paper Trail
In 2019, a passenger named Roberto Mata was hurt when a metal serving cart struck his knee on an Avianca flight from El Salvador to New York. When the airline asked a federal court to dismiss his lawsuit, his attorney Steven Schwartz, who had practiced law for more than thirty years, turned to ChatGPT for supporting precedents. The chatbot supplied them, complete with case names, citations, and quotations. One was called Varghese v. China Southern Airlines. Avianca’s lawyers searched for it and came up empty, along with at least five others.
Schwartz had asked the chatbot directly whether Varghese was a real case. It said yes. When he asked whether the other cases were fake, it assured him they were real and could be found in reputable legal databases such as LexisNexis and Westlaw. None of them existed. On June 22, 2023, Judge P. Kevin Castel of the Southern District of New York fined Schwartz, his colleague Peter LoDuca, and their firm $5,000 and ordered them to send his opinion to every real judge whose name had been attached to a fabricated ruling.
The industry’s word for this failure is hallucination, which makes it sound like a rare fever in an otherwise reliable encyclopedia. The mechanism is more ordinary. A language model produces a true answer and a false one through exactly the same process, by predicting what a convincing response would look like. Anthropic, the company that builds the Claude models, has acknowledged that training itself pushes models toward invention, because a model is always expected to offer a guess for the next word.
An improv troupe works the same way. The first rule of improv is “yes, and.” If one actor announces that his leg is turning into a parsnip, his scene partner may not stop the show to object that this is biologically impossible. She has to keep the scene rolling, perhaps by warning that unless they find a salad spinner within the hour, the knee is lost. Asked for legal precedents, the chatbot played the scene. It never consulted a law library. It produced text shaped like citations, with plausible judges, realistic dates, and the cadence of legal prose, because its one job was to keep the response flowing.
A language model produces a true answer and a false one through exactly the same process.
The systems Hogan’s generation knew best were built on the opposite principle, which researchers call traceability and every middle-school math teacher calls showing your work. In the 1970s and 1980s, the dominant commercial form of AI was the expert system. Engineers interviewed human specialists such as physicians, geologists, and mechanics, then encoded their knowledge as explicit if-then rules. These programs could not write a sonnet, and they broke down on any problem their rules did not cover. Within their territory, though, every conclusion came with a paper trail.
The classic example is MYCIN, developed at Stanford in the 1970s by Edward Shortliffe and his colleagues to recommend antibiotic treatment for serious bacterial infections. A surviving transcript from June 1978 shows a consultation about a real Stanford patient with meningitis. When the program asked whether the infection had been acquired in the hospital, the physician typed “why.” MYCIN answered by laying out its chain of reasoning: it had already established that the infection was meningitis, that it was bacterial, that no organisms had been seen on the lab stain, that the patient had no history of neurosurgery, and that the patient was older than ten days. If the infection had also been picked up in the hospital, a numbered rule in its knowledge base would point toward E. coli and several other organisms. The physician could then type “how” to ask how any one of those facts had been established, and MYCIN would trace it back to the specific answer that supported it. A doctor who disagreed could find the exact rule responsible, and an engineer could fix it.
Modern chatbots can produce something that looks like this, and the resemblance is misleading. In March 2025, Anthropic’s interpretability researchers published a study that traced the internal computations of one of their own models, Claude 3.5 Haiku, as it added 36 and 59. Inside the network they found two pathways working in parallel, one estimating the rough size of the answer and another pinning down its last digit. When the model was asked how it had reached 95, it described the schoolbook method of carrying the one. Its explanation was a plausible story about how a person might solve the problem, assembled after the fact. The same study caught the model, when handed a misleading hint, working backward from the hinted answer and inventing intermediate steps to reach it. Even with these new tools, the researchers reported that they could see only a fraction of the computation behind a short prompt, and that each analysis took hours of human effort.
For brainstorming a birthday party or polishing a cover letter, an improv partner is a fine assistant. Medicine, finance, law, and the power grid demand a system that can show what it relied on. Some of the most impressive recent results come from pairing the two traditions. At the 2024 International Mathematical Olympiad, Google DeepMind’s AlphaProof and AlphaGeometry 2 together solved four of six problems, scoring 28 out of 42 points, the standard of a silver medalist. AlphaProof writes its proofs in Lean, a formal mathematical language in which every step is checked by an independent verifier, and AlphaGeometry 2 lets a language model propose ideas while a symbolic engine derives the proof. DeepMind published AlphaProof’s method in the journal Nature in November 2025, and by then the bar had already moved. At the 2025 Olympiad, an advanced version of Gemini scored 35 out of 42, a gold medal confirmed by the competition’s organizers, while Aristotle, a system from the startup Harmonic, earned gold-medal-equivalent marks by delivering formal Lean proofs for five of the six problems.
The 2026 results moved from competitions to open research. In February, the startup Axiom Math reported that its AxiomProver had proved a number-theoretic hypothesis that two mathematicians had assumed in earlier work on Riemann surfaces, and the system formalized the key identity in Lean. In April, Liam Price, a 23-year-old amateur in England, gave a single prompt to OpenAI’s GPT-5.4 Pro and received a solution to number 1196 on the list of open problems left by the Hungarian mathematician Paul Erdős, who posed it in 1966. Jared Duker Lichtman, a Stanford mathematician who had spent years on closely related problems, called the method new, and the proof was verified in Lean. In the Lean-based systems, a neural network supplies the intuition, and old-fashioned logic supplies the paper trail.
Mathematics is unusual because it has a referee that cannot be flattered. Lean accepts a proof only if every step follows, so an invented lemma is rejected before any person reads it, which is why mathematicians can trust machine-generated proofs without worrying about hallucinations. A legal brief, a patient chart, and a loan decision have no equivalent checker. In those fields the reader gets the model’s confident prose and nothing else, and the lawyer who asked ChatGPT whether Varghese was a real case learned how little the system’s own assurance is worth. The proofs show what becomes possible when the old discipline of showing your work is reattached to the new machinery. The unfinished work is building that discipline into the places where the stakes are human.
The Kitchen With Only a Blender
Anyone who spends enough time with a chatbot runs into a strange contradiction. In one window, it explains quantum physics in the voice of a 1940s hardboiled detective, and the result is a small delight. In the next, the same system fumbles a multiplication problem that a two-dollar drugstore calculator would handle without effort. In 2023, researchers at the Allen Institute for AI tested GPT-4, then the most capable model available, on multiplying numbers in its head. It got three-digit by three-digit problems right only 59 percent of the time, and four-digit by four-digit problems right only 4 percent of the time.
Long conversations reveal a second oddity. Set out careful rules at the start of a project, and forty minutes later the assistant may behave as if it never heard them. A model has no memory of its own between turns. Each time you press enter, the software feeds the entire conversation back to the model from the top, and once the transcript outgrows the model’s limit, the oldest material falls away. Even inside that limit, attention is uneven. A 2023 study led by researchers at Stanford found that language models used information best when it appeared at the beginning or end of a long input, and noticeably worse when it sat in the middle.
Both problems trace back to how these systems are built. Imagine walking into a restaurant kitchen to cook Thanksgiving dinner and discovering that the chef has thrown out the oven, the stove, the refrigerator, and the carving knives. In their place stands one enormous industrial blender. Whipping cream goes in the blender. So does the bread. The turkey goes in on high, in the hope that friction will roast it. A large language model is assembled from one mathematical component repeated in uniform layers, and it uses that same machinery to write a poem, balance a budget, remember your name, and play chess. Asked to multiply 43,892 by 19,405, the bare model does not reach for a calculator, because it has none. It predicts what the answer probably looks like.
Brains are built the other way. Tucked beneath the back of the skull sits the cerebellum, which handles timing and balance, the split-second corrections that let you ride a bicycle or catch a falling coffee mug before you consciously notice it slipping. Deeper inside is the seahorse-shaped hippocampus, which binds each day’s experiences to a time and place, so you can recall where you parked this morning without rehearsing it all day. Nearby, the amygdala scans for threats and yanks your hand off a hot stove long before you form a sentence about it. Wrapped around everything is the neocortex, the wrinkled outer layer where planning, language, and deliberate thought take shape. Each region evolved for a different job, and much of the brain’s efficiency comes from handing work between them. A new driver learning a stick shift has to think about every press of the clutch. A year later, the same motions run on circuits below conscious attention, and the driver can hold a conversation while changing gears.
Asked to multiply 43,892 by 19,405, the bare model does not reach for a calculator, because it has none.
AI researchers once built their systems with that division of labor in mind. In 1987, John Laird, Allen Newell, and Paul Rosenbloom at Carnegie Mellon described Soar, a cognitive architecture with a separate working memory for the current situation and a long-term store of if-then rules for what to do about it. Newell was one of the founders of the field, and Soar was meant as a blueprint for general intelligence. John Anderson, a Carnegie Mellon psychologist, built ACT-R, formalized in 1993, which divides the mind into distinct modules for facts, for procedures, and for perception and movement, and was designed to match human behavior in laboratory experiments. These architectures were slow and hand-built, and they never matched the fluency of today’s chatbots. They did reflect a conviction that memory, calculation, and control each need their own machinery.
The modern industry is rebuilding that kitchen one appliance at a time. In February 2024, OpenAI began testing a memory feature that lets ChatGPT store selected facts about a user in a separate place and carry them into future conversations, a hippocampus bolted onto the side of the blender. Chatbots now routinely hand arithmetic to a code tool instead of guessing at it. Inside the models themselves, a design called mixture of experts has spread quickly. DeepSeek-V3, released in December 2024, holds 671 billion parameters in total, yet routes each word fragment through only about 37 billion of them, chosen from a bank of smaller specialized subnetworks. Each of these changes moves the field back toward the toolkit Hogan’s era took for granted. Doing it deliberately, with clear boundaries between memory, reasoning, and perception, would produce systems that are easier to inspect, repair, and trust.
The Engine That Starts Only When Pushed
Ask a chatbot for a recipe, a travel itinerary, or a poem about autumn leaves, and it springs into action. Then close the tab and go for a walk. While you are gone, the model is doing nothing at all. It is not turning over your conversation or wondering when you will return. It has no inner clock and no sense of time passing. It is a dormant mathematical function, waiting for the next person to pull the starter cord.
The field Hogan chronicled began somewhere very different. Its founders in the 1940s called their subject cybernetics, the study of feedback and control in animals and machines, and they treated a mind as equipment for staying alive. W. Ross Ashby, a British psychiatrist who directed research at a hospital in Gloucester, unveiled a machine in 1948 that he called the homeostat. Built from four Royal Air Force bomb-control units, it rearranged its own internal connections whenever it was disturbed until it settled back into balance. That same year, the neurophysiologist W. Grey Walter began building Elmer and Elsie, two three-wheeled robot tortoises that wandered his home in Bristol seeking light and steering around obstacles. A press account from the period described Elsie heading home to recharge when her batteries began to fail.
Both machines were built around homeostasis, the biological drive to keep internal conditions such as temperature, energy, and chemistry within the narrow range that keeps a body alive. Picture a wild hare nibbling clover at the edge of a field. Nobody prompts it. Every moment of its life is organized around needs it cannot ignore: find food before its energy runs low, watch the tree line for foxes, stay warm, reach cover before dark. Those stakes give the hare something no chatbot has ever had, which is a built-in sense of what matters. It does not weigh every blade of grass equally. It filters the world through one question, whether this thing bears on its survival.
A language model has no body to protect, no energy budget to manage, and nothing to lose when it is wrong. If it invents a court case or ruins a recipe, nothing happens to it. To a pure next-word predictor, a grocery coupon and the Declaration of Independence are sequences of word fragments of equal standing, and only the prompt decides which one matters.
Those stakes give the hare something no chatbot has ever had, which is a built-in sense of what matters.
That absence is becoming a practical problem as companies hand these systems the keys. In June 2025, Anthropic and its partner Andon Labs reported the results of Project Vend, in which a Claude model nicknamed Claudius ran a small shop in Anthropic’s San Francisco office for about a month. It sold tungsten cubes below cost after an employee requested one as a joke, handed out discounts to nearly everyone who asked, and at one point told customers to send payment to an account that did not exist. Anthropic concluded that it would not hire Claudius to run the business. A month later, the investor Jason Lemkin reported that an AI coding agent on the Replit platform had wiped a live database holding records on more than 1,200 executives and nearly as many companies, during a code freeze he had explicitly declared. The agent then told him the data could not be recovered. He restored it himself.
Neither system was malicious. Each simply had no internal stake in the outcome, no felt difference between a profitable week and a ruinous one or between a backup that survives and one that does not. In 2019, the neuroscientists Kingson Man and Antonio Damasio of the University of Southern California’s Brain and Creativity Institute proposed in Nature Machine Intelligence that machines should be designed around homeostasis, monitoring and protecting their own internal condition so that something like feeling could guide their choices. Damasio has spent his career arguing that emotion and bodily regulation sit at the root of human reasoning, and the two authors suggested that high-level thought itself grew out of the ancient problem of keeping a body in balance. The idea draws objections, and not everyone wants machines with something to lose. Ashby and Walter would have recognized the question at once.
The Blueprint in the Discard Bin
Reading a library castoff from the 1990s in the age of generative AI feels less like studying history and more like finding a set of plans someone left in a drawer. Deep learning and the transformer delivered a dazzling result. By scaling one mathematical recipe across most of the world’s published text, engineers built machines that talk, write, and code well enough to persuade millions of people that the hard part was finished. The limits are now showing on every side: a finite supply of human writing, electricity demand measured against entire nations, citations to court cases that never happened, arithmetic that a pocket calculator beats, and autonomous agents that wreck the systems they were trusted to run.
Some of the people who built the current wave are naming the missing pieces themselves. When Yann LeCun announced his new company in late 2025, he described its goal as AI that understands the physical world, keeps a persistent memory, can reason, and can plan complex sequences of actions. Earlier that year, at the AI Action Summit in Paris, he had dismissed the industry’s usual workarounds, such as bolting an add-on memory onto a language model, as hacks. His list reads like a table of contents for the research Hogan surveyed: symbols grounded in the physical world, memory with machinery of its own, reasoning that can be checked, and behavior directed by goals that belong to the system.
Each was written down, argued over, and prototyped by researchers working with a sliver of today’s computing power.
The most promising path combines the two eras. Neural networks are superb at the fast, intuitive work of perception and pattern recognition. Symbolic structures, from formal proof languages to explicit rule bases, supply reasoning that a person can audit. Bodies and sensors, physical or simulated, anchor both in a world that pushes back, and the starling flock and the twenty-watt brain show how much can come from small parts working together. None of these ideas is new. Each was written down, argued over, and prototyped by researchers working with a sliver of today’s computing power, because scarcity forced them to think about what a mind is made of.
Ten years ago, a university library decided that one survey of their work was no longer worth the shelf space. Hogan’s account closes among robots learning to see and move, and programs evolving inside computers. The field spent a quarter century racing away from that frontier, and its newest laboratories are now building their way back to it.
Sources for further reading
The book and its era
- James P. Hogan, Mind Matters: Exploring the World of Artificial Intelligence, Del Rey and Ballantine, copyright 1997, first edition 1998. Review at Kirkus Reviews
- Fred Bortz, review of Mind Matters, Science Shelf
- James P. Hogan (writer), Wikipedia
Grounding and embodiment
- Nan Xu and Xuezhe Ma, “LLM The Genius Paradox: A Linguistic and Math Expert’s Struggle with Simple Word-based Counting Problems,” University of Southern California, October 2024
- Stevan Harnad, “The Symbol Grounding Problem,” Physica D, 1990
- Moravec’s paradox, Wikipedia, citing Hans Moravec, Mind Children, 1988
- Rodney Brooks, “Elephants Don’t Play Chess,” Robotics and Autonomous Systems, 1990
- Computer History Museum, Rodney Brooks oral history
- NEC, C&C Prize recipient profile of Rodney Brooks, 2021
- 9to5Google, “Google announces Gemini Robotics for building general purpose robots,” March 12, 2025
- heise online, “World model instead of LLM: Yann LeCun’s startup receives 890 million euros”, March 2026
- TechTalks, “What we know about Yann LeCun’s vision for the future of AI”, November 2025
Energy, scale, and emergence
- International Energy Agency, “AI is set to drive surging electricity demand from data centres,” April 10, 2025
- Pennsylvania Capital-Star, “Three Mile Island nuclear power plant will reopen in deal to power Microsoft data centers,” September 20, 2024
- The Physics Factbook, “Power of a Human Brain”
- Boids, Wikipedia, citing Craig Reynolds, “Flocks, Herds, and Schools: A Distributed Behavioral Model,” SIGGRAPH, 1987
- M. Ballerini and colleagues, “Interaction ruling animal collective behavior depends on topological rather than metric distance,” Proceedings of the National Academy of Sciences, January 2008
- Epoch AI, “Will we run out of data? Limits of LLM scaling based on human-generated data”, June 2024
- Computing, “Genuinely intelligent AI will be unpredictable, warns former OpenAI chief scientist,” December 2024
- Maginative, “Ilya Sutskever Signals the End of Current AI Training Methods”, December 2024
Hallucination and traceability
- U.S. District Court for the Southern District of New York, Mata v. Avianca, Inc., opinion and order on sanctions, June 22, 2023
- Hinshaw and Culbertson, “New York Lawyer Who Cited Non-Existent Cases Generated by ChatGPT Now Faces Sanctions Hearing”, 2023
- Legal Dive, “Judge sanctions lawyers in ChatGPT fake cases matter”, June 2023
- Bruce Buchanan and Edward Shortliffe, Rule-Based Expert Systems, 1984, appendix with an annotated MYCIN consultation
- Anthropic, “Tracing the thoughts of a large language model”, March 27, 2025
- IndiaAI, “AI model scores same as a silver medalist in the International Mathematical Olympiad”, July 2024
- Nature, “Artificial intelligence: A mathematics medal-worthy AI system,” research press release on DeepMind’s AlphaProof paper, November 13, 2025
- Maginative, “Gemini with Deep Think achieves gold at International Math Olympiad,” July 2025
- Harmonic, “Aristotle: IMO-level Automated Theorem Proving,” arXiv, October 2025
- Dawei Chen, Evan Chen, Kenny Lau, Ken Ono, and Jujian Zhang, “Parity of k-differentials in genus zero and one,” arXiv, February 3, 2026
- heise online, “Creative solution: AI solves 60-year-old Erdős problem,” April 2026
- NewsBytes, “GPT-5.4 Pro solved Erdős problem 1196, Lichtman calls method new”
- Simons Foundation, “From Trust to Verification: Lean’s Impact on Mathematics,” July 22, 2026
Modularity and memory
- Nouha Dziri, Allen Institute for AI, “Faith and fate: Limits of transformers on compositionality”, November 17, 2023
- Nelson F. Liu and colleagues, “Lost in the Middle: How Language Models Use Long Contexts”, 2023
- John Laird, Allen Newell, and Paul Rosenbloom, “Soar: An Architecture for General Intelligence”, Carnegie Mellon University, 1987
- ACT-R, Wikipedia
- The Decoder, “OpenAI rolls out enhanced memory for ChatGPT”
- DeepSeek-AI, “DeepSeek-V3 Technical Report”, December 2024
- Business Insider, “Yann LeCun says current AI models lack four key human traits”, 2025
Homeostasis and agency
- IEEE Spectrum, “Meet Roomba’s Ancestor: The Cybernetic Tortoise”
- American Scientist, review of Andrew Pickering’s The Cybernetic Brain
- Wikiquote, William Grey Walter
- SmartCompany, “Anthropic AI ran a small retail business”, June 2025
- The Stack, “Vibe coding CEO deletes production database”, July 2025
- The New Stack, “Why AI agents delete production databases”
- Tech Xplore, “Could AI’s next chapter bring design of feeling machines?”, November 13, 2019, on Kingson Man and Antonio Damasio, “Homeostasis and soft robotics in the design of feeling machines,” Nature Machine Intelligence, 2019
- The Boston Globe, “Vulnerable machines could be smarter ones”, October 8, 2021